ΑΙhub.org
Optics lens design for privacy-preserving scene captioning: interview with Carlos Hinojosa
Paula Arguello, Jhon Lopez, Carlos Hinojosa and Henry Arguello won the best paper award at the International Conference on Image Processing (ICIP) this year, for their work Optics lens design for privacy-preserving scene captioning. In this interview, Carlos tells us more about privacy-preserving scene captioning, how they approached the problem, and the key contributions of their work.
What is the topic of the research in your paper?
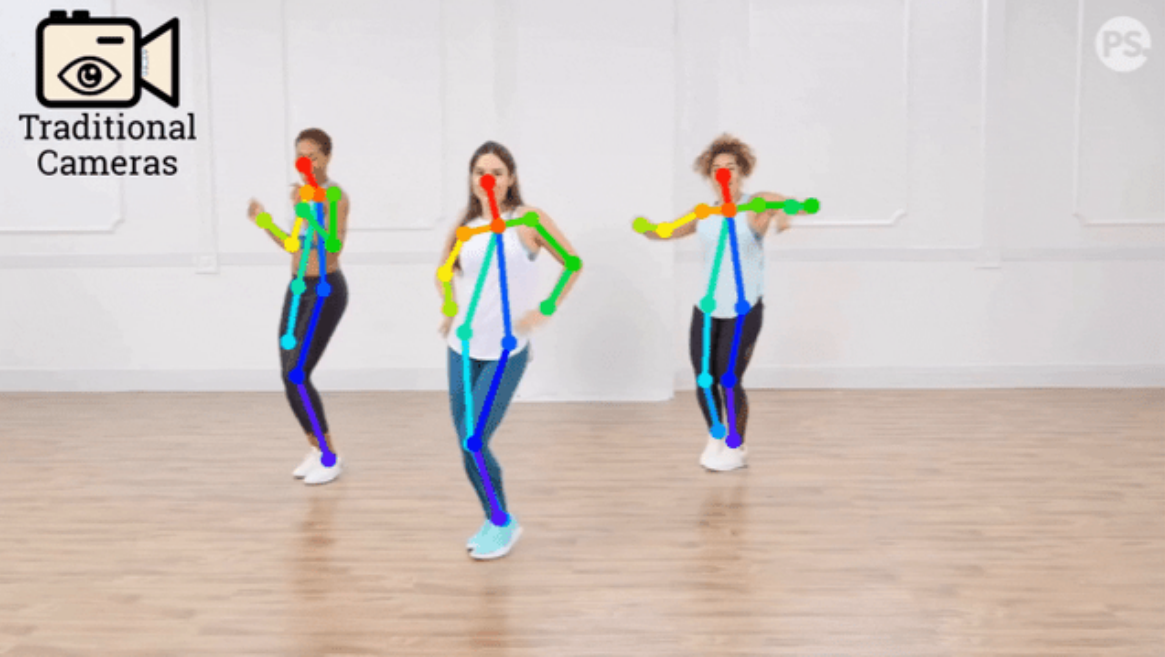
We have digital cameras everywhere. They are fundamental to a range of intelligent systems that recognize relevant events and assist us in our daily activities. We have them in our cars, homes, hospitals, etc. However, their ever-improving ability to imitate the human vision system and produce the highest-quality images has raised concerns about privacy and security. Inspired by the trend of jointly designing optics and algorithms, our research addresses the problem of privacy-preserving in computer vision and image processing. Specifically, in our last paper we developed a privacy-preserving algorithm for scene captioning. This paper was presented at the IEEE International Conference on Image Processing (ICIP) 2022 [1] and won the best paper award. We also have published similar works on privacy-preserving human pose estimation [2] and human action recognition [3] at the International Conference on Computer Vision (ICCV 2021) and European Conference on Computer Vision (ECCV 2022), respectively. Previous privacy-preserving works in computer vision have focused on developing software-level processing solutions on the already acquired high quality images/videos, but this could lead to a lack of privacy as the original images/videos are unprotected. I proposed to address this problem within the camera hardware itself.
Could you tell us about the implications of your research and why it is an interesting
area for study?
Traditionally, computer vision systems are implemented to perform computer vision tasks such as action recognition, pose estimation, and image captioning, but such systems imitate the human vision system. Therefore, if an adversary gets access to the system’s camera, it could intrude on or violate user privacy. However, a machine does not actually need to ‘see’ like humans to perform a vision task. In fact, we demonstrate that the machine can still extract useful features from distorted images that allow us to train a deep neural network and perform a computer vision task. Our work has several potential applications. In hospitals, for example, where vision systems perform vital computer vision tasks, our model could help preserve patients’ privacy, with the added benefit of enabling the collection of anonymized patient data that could be used for further research. It could also be used at home to monitor older adults’ activity and detect with sufficient time if they fall without intruding on their privacy. Our previous work on privacy-preserving human pose estimation could also be implemented in surgical rooms to monitor the movement of patients and doctors.
Could you explain your methodology?
The main idea of our work is to design the camera lens jointly with a deep neural network that performs a computer vision task. Our lens design consists of adding optical aberrations to the lens rather than removing them as traditional lens design does. The result is a camera that acquires highly distorted images and videos. However, note that this optical design is not random. Specifically, we optimize the optics (to provide hardware-level protection) with a deep neural network in an end-to-end framework. Therefore, we backpropagate the gradients from the last layers of the deep neural network to the lens. This allows us to conduct the optimization so the deep neural network extracts useful features from the highly distorted images/videos, but at the same time, we inhibit privacy-related features like human faces. In the last three years, we have proposed different optimization strategies and addressed different computer vision tasks in three papers. One of them won the best paper award in ICIP 2022 [1], and the other two were selected for oral presentations in the ICCV 2021 [2] and ECCV 2022 [3] (chosen among the top 3% from all submissions). Furthermore, we have two patents in progress around these optimization strategies in collaboration with Stanford University.
What were your main findings?
We validate our approach with extensive simulations and a prototype camera. Our main findings are as follows:
- We show that our privacy-preserving approach successfully degrades or inhibits private attributes while maintaining essential features to perform computer vision tasks.
- The trained deep neural network that performs the computer vision tasks can perform on the highly distorted data.
- During the optimization, there is a trade-off between distortion/privacy and accuracy. Using a lens that distorts too much could decrease the performance of the deep neural network.
- We trained blind and non-blind deconvolution networks to recover the original images from the distorted images obtained by our camera. We found that deconvolution is challenging, and the algorithms cannot reconstruct details in images like human faces.
What further work are you planning in this area?
We are currently developing different optimization approaches and addressing different computer vision tasks. We are also designing a different hardware setup and implementing different optical strategies to perform distortions. Furthermore, we are interested in acquiring a large-scale dataset with our proposed camera.
References
[1] P. Arguello, J. Lopez, C. Hinojosa, and H. Arguello. Optics Lens Design for Privacy-Preserving Scene Captioning. In IEEE International Conference on Image Processing (ICIP) 2022.
[2] C. Hinojosa, J. C. Niebles, & H. Arguello. Learning privacy-preserving optics for human pose estimation. In Proceedings of the IEEE/CVF International Conference on Computer Vision 2021.
[3] C. Hinojosa, M. Marquez, H. Arguello, E. Adeli, L. Fei-Fei, & J. C. Niebles. PrivHAR: Recognizing Human Actions From Privacy-preserving Lens. European Conference on Computer Vision (ECCV) 2022.
About the author
|
Carlos Hinojosa received his B.Sc., M.Sc., and Ph.D. degrees in computer science in 2015, 2018, and 2022 respectively, from the Universidad Industrial de Santander, Bucaramanga, Colombia. He was an intern researcher at the Stanford Vision and Learning Lab (SVL) at Stanford, where he was under the supervision of Prof. Juan Carlos Niebles. His research work is at the intersection of computer vision and computational imaging. Specifically, his research focuses on designing computational imaging systems and developing novel computer vision algorithms to improve final vision tasks while obtaining benefits from the optics like privacy protection, compression, etc. His research starts with the camera itself (hardware) and finishes with developing novel computer vision algorithms (software). |
Find out more
Here are the project pages for this, and related, work:
Optics lens design for privacy-preserving scene captioning
Learning privacy-preserving optics for human pose estimation
PrivHAR: Recognizing Human Actions From Privacy-preserving Lens
AUAI is supported by: