ΑΙhub.org
How AI is opening the playbook on sports analytics
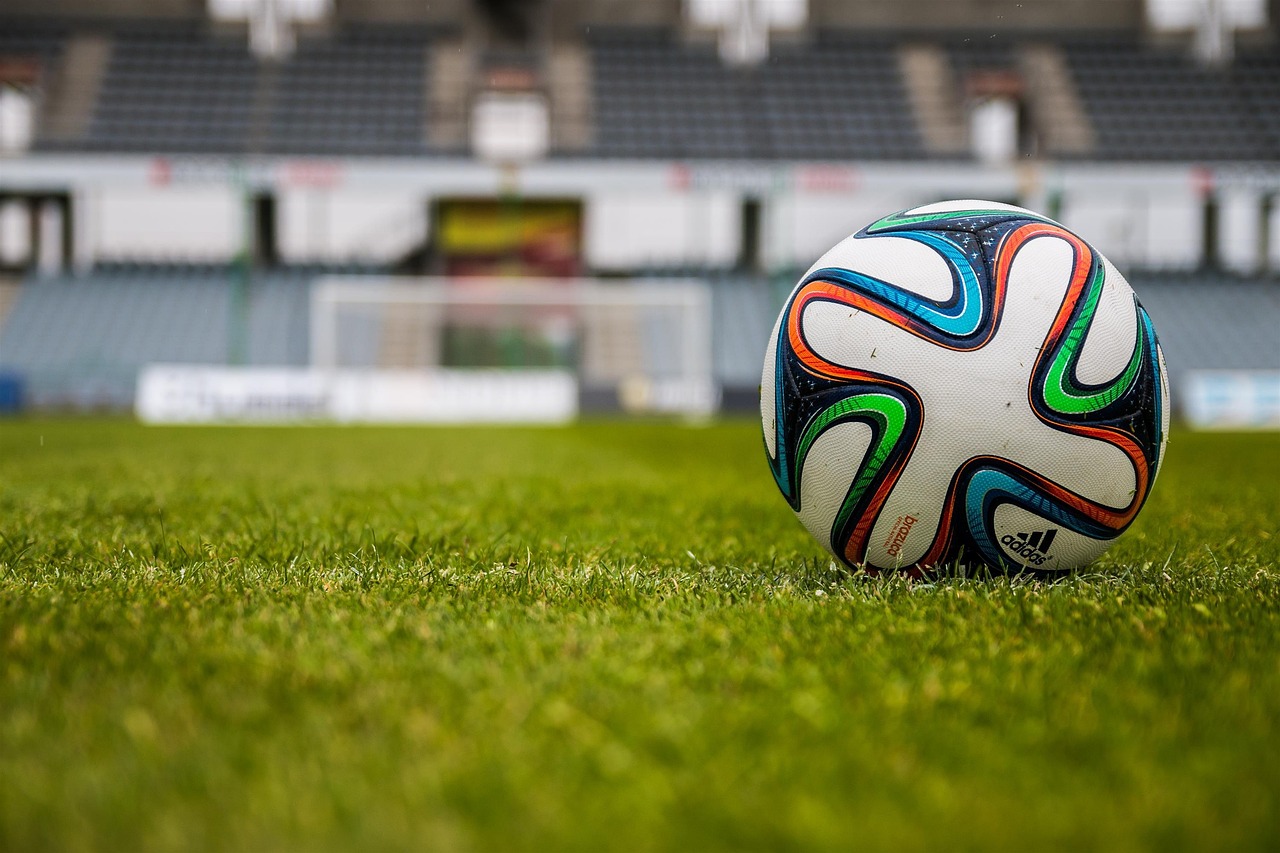
Professional sports teams pour millions of dollars into data analytics, using advanced tracking systems to study every sprint, pass, and decision on the field. The results of that analysis, however, are industry secrets, making many sports difficult for researchers to study.
Now, two University of Waterloo researchers, Dr. David Radke and Kyle Tilbury, are using AI to level the playing field.
By tapping into Google Research Football’s reinforcement learning environment, the researchers developed a system that can simulate and record unlimited soccer matches. To get things started, they generated and saved data from 3,000 simulated soccer games, resulting in a rich and complex dataset of passes, goals, and player movements for researchers to study.
“While researchers have access to a lot of data about episodic sports like baseball, continuous invasion-game sports like soccer and hockey are much more difficult to analyze,” said Radke, a recent Waterloo PhD graduate in computer science and currently a senior research scientist for the NHL’s Chicago Blackhawks.
“While the AI-generated players might not exactly play like Lionel Messi, the simulated datasets they generate are still useful for developing sports analysis tools.”
Datasets like the ones generated by the team are particularly useful for researchers, enthusiastic fans, and smaller research teams that may not have extensive access to proprietary sports data.
“Enabling researchers to have this data will open up all kinds of opportunities,” said Tilbury, a Waterloo PhD student in computer science who equally co-authored the research. “It’s a democratization of access to this kind of sports analytics data.”
While datasets like the one generated by the team are particularly interesting for sports enthusiasts, they have larger implications for AI research as well.
“At its core, invasion-game sports analytics is about understanding complex multiagent systems,” Radke said. “The better we are at modelling the complexity of human behaviour in a sporting situation, the more useful that is for AI research. In turn, more advanced multiagent systems will help us better understand invasion-game sports.”
Radke and the team believe the future of sports analytics relies on progress in the space of tracking data. They therefore hope researchers interested in sports without access to tracking data will utilize their datasets and repository to gain experience working with this type of data.
The study, Simulating tracking data to advance sports analytics research, appeared in the proceedings of the 24th International Conference on Autonomous Agents and Multiagent Systems.
tags: AAMAS
AUAI is supported by: