ΑΙhub.org
#NeurIPS2021 invited talks round-up: part one – Duolingo, the banality of scale and estimating the mean
The 35th conference on Neural Information Processing Systems (NeurIPS2021) started on Monday 6 December 2021. There are eight invited talks at the conference this year. In this post, we give a flavour of the first three, which covered a diverse range of topics.
How Duolingo uses AI to assess, engage and teach better
Luis von Ahn
Duolingo is the world’s most downloaded educational app, with around 500 million downloads to date. In his talk, co-founder and CEO Luis described the different ways in which the Duolingo team use AI. This includes trying to improve their curriculum, keeping their learners engaged, and assessing translations.
The Duolingo team have a huge amount of user data at their disposal. Each language course is split into different skills, and within each skill there are a selection of exercises to complete. Information is collected from about 600 million exercises every day. All of this data is used to try and improve aspects of the app and the learning process.
The first use of AI that Luis mentioned pertains to the curriculum – basically the order in which the different skills are taught. They experiment with changes in the order in which they teach particular skills, and using the results of users’ scores on the exercises, they can adapt the curriculum accordingly.
Luis also talked about a system they have developed called Birdbrain. Through logistic regression, Birdbrain personalises every lesson for every user. Every exercise that a user completes is recorded and their data (along with global data for all users) is used to optimise future lessons. With this huge model they are able to predict the probability with which a particular user will get a particular exercise correct. They try to teach in the zone of proximal development, where learners are given exercises that are just a little bit too hard for them, but not too difficult. They aim to give users exercises where there a probability of success of around 80%.
Other uses of AI are in grading translations, and in providing users hints (smart tips) as to why a particular answer they gave might be wrong.
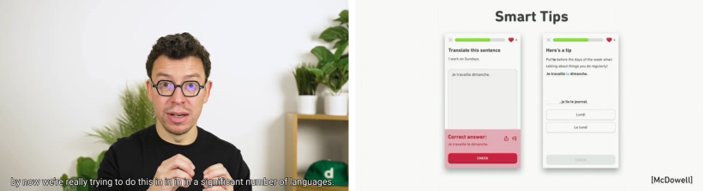 Screenshot from Luis’ talk. On the right is an example of one of the “smart tips”.
The banality of scale: a theory on the limits of modelling bias and fairness frameworks for social justice (and other lessons from the pandemic)
Mary Gray
Since the beginning of the pandemic, Mary has been studying the workflows and data needs of community healthcare workers in North Carolina who are driving vaccine equity in black and latinx communities. The research question she posed was: “how might we harmonize technological innovation to meet the immediate and shared needs, not of individual users,… but to imagine how we build systems for groups of people who are creating and maintaining networks of collaboration and social connection”.
A thread that ran through the talk was the need to work with domain experts in social science, and to work with these experts throughout the entire planning, development, implementation, and improvement cycle of deployed AI systems. She pointed out that work in the social sciences is just as technical as anything one might hear at the computer science conference. However, these researchers are not invested in causal inference or discrete measurement. Social scientists create datasets of experiences through working with domain experts, to produce theories without attachment to being able to control what they theorise could happen next. She noted that it’s difficult for people to recognise the contribution of fields such as social science as there is no easy way to discretely measure them.
In the talk she advocated for understanding more deeply why it is that machine learning gravitates towards large datasets as the coveted object of analyses, even though it’s rare that there is a robust account of where the data comes from. The data is often disconnected from the social relationships that produced it.
The one key message that Mary wanted listeners to take away from the talk was that data is power. Her argument is that because data has become so powerful, we should make it our collective responsibility to transfer the tools of data collection to the communities carrying the benefits and risks of what can be built. Rather than searching for more and more data to “balance out” a model, we could consider shifting to building models to be iterative, using subject expertise to adapt to changing scenarios. Instead of trying to override bias with a system, models could be used to raise awareness of bias.
Mary closed her talk by highlighting the importance of multidisciplinary teams, and of taking on board the expertise of domain experts.
 Screenshot from Mary’s talk.
Do we know how to estimate the mean?
Gabor Lugosi
In his talk, Gabor focused on what he described as perhaps the most basic problem in statistics: estimating the mean. In other words, estimating the expected value of a random variable when we are given independent, identically distributed random variables.
For the first part of the talk, he concentrated on the real values case. If you want to estimate the mean, the obvious first choice is to take the empirical mean. We know that the expectation value is correct and that if we add more and more numbers to our dataset, we will converge on the true mean regardless of the distribution. However, if we don’t know anything about the distribution, other than the existence of expectation, then this convergence can be arbitrarily slow. This is true for any function.
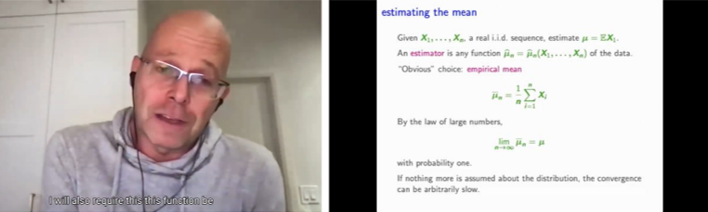 Estimating the mean. Screenshot from Gabor’s talk.
In his research, Gabor has been investigating better estimators than the empirical mean, and he showed us two of them in the talk. One of these is the so-called median of means, which goes back to the 1980s. The trick is to divide the data into blocks and within each block the empirical mean is calculated, and then the median of these blocks is taken as the mean.
Another option is to use the trimmed mean, one of the oldest ideas in robust statistics. This is particularly effective when you have heavy-tailed data. Basically, you just truncate the data to chop off the outliers, and then take the empirical mean of the rest.
In the second part of his talk, Gabor considered multivariate distributions. In these cases, what we’d like to estimate is the expected value of a random vector. He expanded the ideas covered in the first part – the median of means, and the trimmed mean – for the case of multivariate distributions.
tags: NeurIPS, NeurIPS2021
AUAI is supported by: