ΑΙhub.org
When compression techniques don’t just add up: Interaction effects in hybrid LLM compression
What happens when you shrink a language model twice — once by removing some of its weights, once by storing what’s left with fewer bits? You’d guess the damage just adds up. It doesn’t.
The problem: does compression just add up?
Small language models are increasingly used for on-device apps that need to run in tight memory budgets [Zhou et al. 2025]. To shrink them enough, people often combine two tricks: pruning, which removes some of the model’s weights, and quantization, which stores the remaining weights using fewer bits. Recent work has combined both, often finding the mix beats either trick alone [Kang et al. 2025]. But most of these studies only look at the combined result — they don’t ask whether the two tricks are simply adding their effects together, or doing something else entirely.
We wanted to find out.
A simple test: does it just add up?
To check, we borrowed a simple idea from statistics. For each benchmark, we measure four things: the original model, the pruned-only model, the quantized-only model, and the hybrid. Then we compare:

If the two tricks were simply adding up,  would land close to zero. If is positive, the hybrid does better than expected. If it’s negative, the hybrid does worse.
We tested this on three small models — Falcon3-1B-Base, LLaMA-3.2-1B, and a quick check on Qwen2.5-1.5B — at different pruning levels and with both 4-bit and 8-bit quantization, all on a single consumer GPU (an RTX 3080 Ti).
What we found: truthfulness up, reasoning down
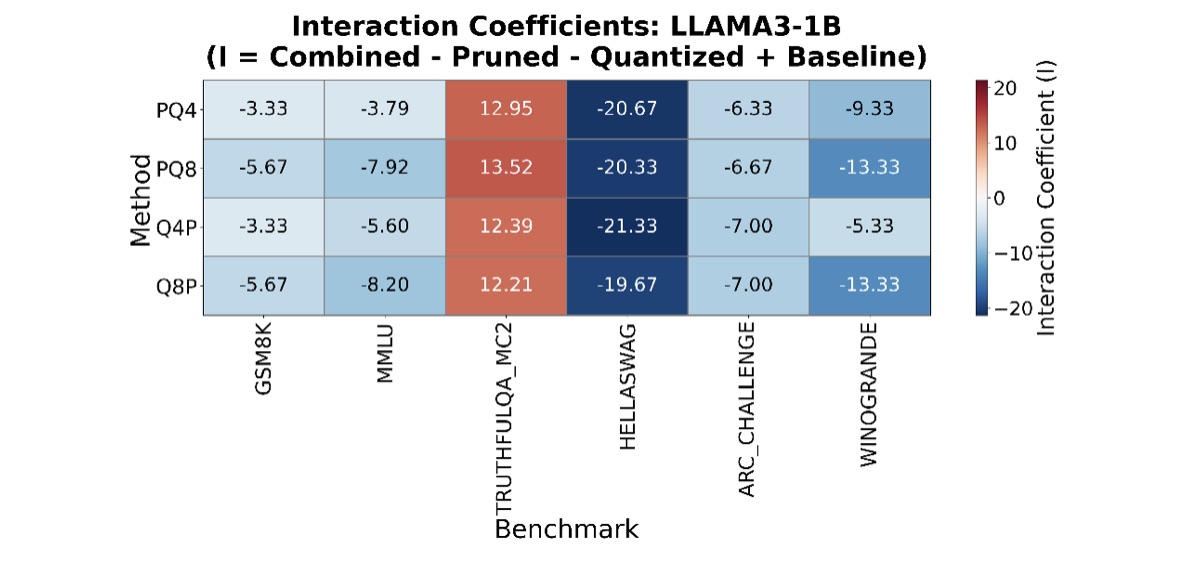
The results split sharply by task. On TruthfulQA, the hybrids consistently beat expectations — by about +7 points on Falcon and +12 to +14 points on LLaMA. It’s as if combining the two tricks accidentally made the models more careful about truthfulness.
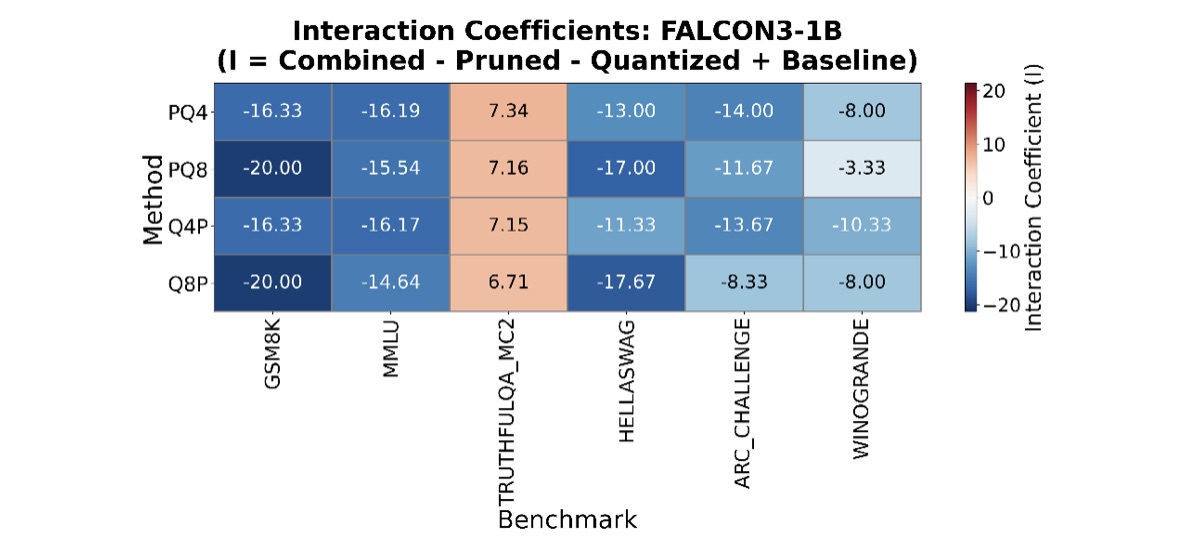
On reasoning and knowledge tasks, the opposite happened. GSM8K (grade-school math) and MMLU (general knowledge) dropped far more than expected — by 16 to 20 points on Falcon. In several hybrid setups, GSM8K accuracy fell all the way to zero.
The twist: more pruning doesn’t mean more damage
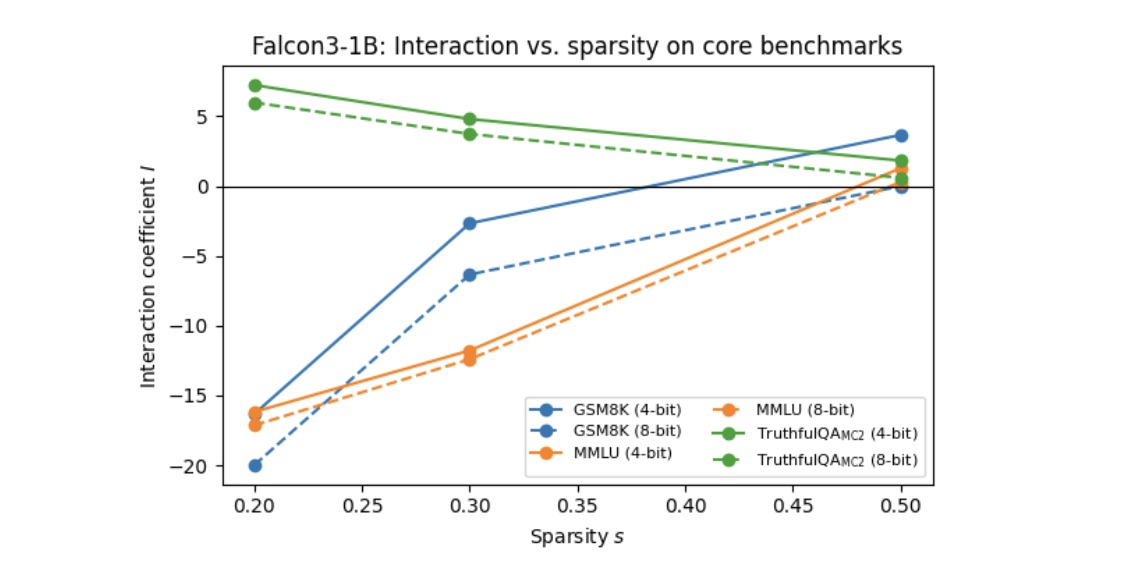
We assumed these effects would get worse the more we pruned. They didn’t. Instead, they peaked at moderate pruning (20–30%) and faded back toward normal at 50% pruning — both the TruthfulQA boost and the reasoning drop. More pruning didn’t mean more damage; it meant the surprise effect faded.
We also found the order barely mattered — quantizing before pruning versus after changed results by only a point or two. What mattered was simply whether the two tricks were combined at all.
What this means for practitioners
If your app cares about factual reliability, moderate hybrid compression might actually help. If it needs strong reasoning or broad knowledge, stick with quantization alone — hybrids can quietly wreck more than you’d expect. And if you just want a smaller model, quantization is doing almost all the work: pruning alone barely changes memory use, while 4-bit quantization cuts it by roughly 2 to 3 times.
The bigger lesson: don’t assume compression tricks just add up. Measure them.
Limitations and future work
We used simple, unstructured pruning without special hardware support, so our memory numbers don’t reflect what’s possible with dedicated sparse hardware. We tested two models closely and one lightly, and none were fine-tuned afterward. Testing more models, hardware-aware pruning, and light fine-tuning (like LoRA) to balance truthfulness gains against reasoning losses are natural next steps.
Find out more
- The paper: Interaction Effects in Hybrid Compression of Small Language Models, presented at IJCAI-ECAI 2026, Bremen
- Code and configurations
References
- Frantar, E. and Alistarh, D. (2023). SparseGPT: Massive Language Models Can Be Accurately Pruned in One-Shot. Proceedings of the 40th International Conference on Machine Learning.
- Frantar, E., Ashkboos, S., Hoefler, T., and Alistarh, D. (2023). GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers. International Conference on Learning Representations.
- Ma, X., Fang, G., and Wang, X. (2023). LLM-Pruner: On the Structural Pruning of Large Language Models. Advances in Neural Information Processing Systems.
- Kang, Y., Luo, Z., Wen, M., Shi, Y., He, J., Yang, J., Xue, Z., Feng, J., and Liu, X. (2025). HWPQ: Hessian-Free Weight Pruning-Quantization for LLM Compression and Acceleration. arXiv preprint.
- Zhou, Z., Kurz, S., and Zhao, Z. (2025). Revisiting Pruning vs. Quantization for Small Language Models. Findings of the Association for Computational Linguistics: EMNLP.
tags: ECAI, ECAI2026, IJCAI, IJCAI2026
AUAI is supported by: